Junjo (順序) - order, sequence, procedure
Junjo AI Studio is an open source, self-hostable AI Agent and Workflow debugging and eval platform for any OpenTelemetry instrumented AI application.
The Junjo Python Library is a framework for structuring AI logic and enhancing Otel span data to improve observability and developer velocity. Junjo remains decoupled from your LLM implementations and business logic, providing a layer of organization, execution, and telemetry to your existing application.
Gain complete visibility to the state of the application, and every change LLMs make to the application state. Complex, mission critical AI workflows are made transparent and understandable with Junjo.
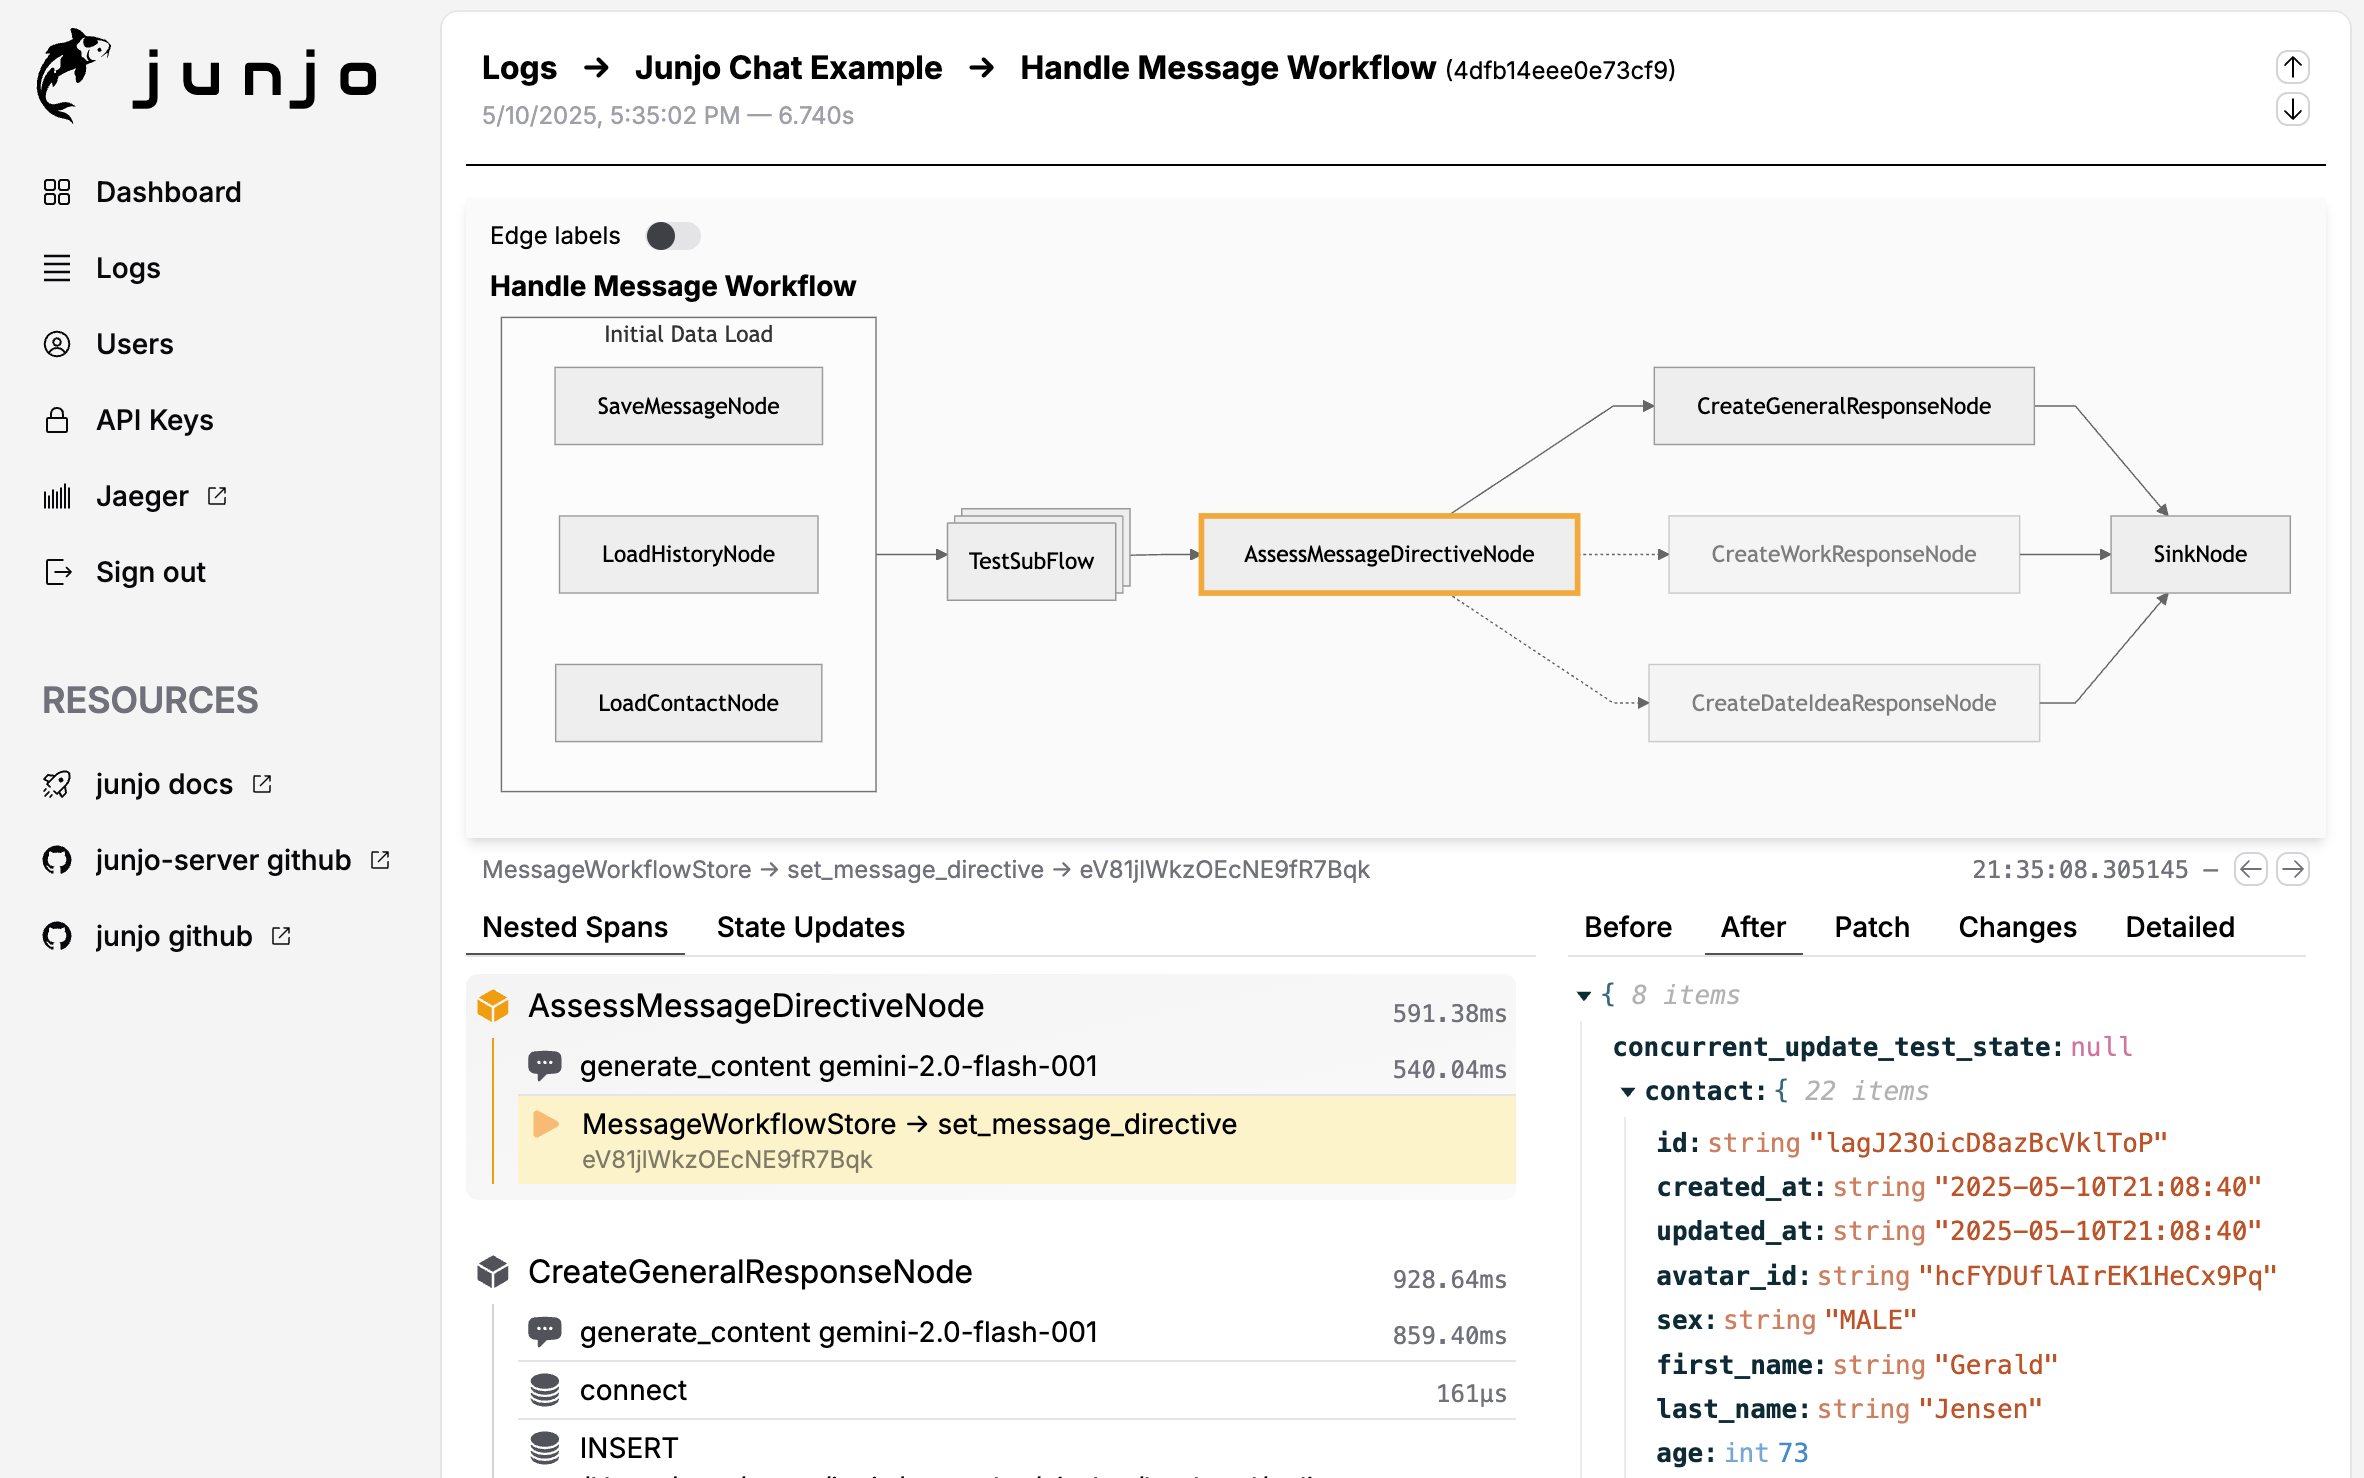

Junjo AI Studio Workflow Debugging Screenshot
- 🔍 Real-time LLM Decision Visibility - See every decision your LLM makes and the data it uses
- 🧭 Agent Execution Diagnostics - Inspect ordered model and Tool operations without fabricating a Graph
- 🔀 Transparent Concurrency - Debug state changes from concurrently executed AI workflow steps
- 📊 OpenTelemetry Native - Standards-based telemetry ingestion via gRPC
- 🎯 Workflow Debugging Interface - Visual step-by-step debugging of AI graph workflows
- 🧾 Evidence Integrity - Verify Store reconstruction, payload availability, loss signals, and nested execution parentage
- 🔒 Production-Ready Security - Authentication, user accounts, and encrypted sessions
- 🚀 Low Resource, High-Performance Ingestion - Designed for high-throughput in low resource environments
- 💾 Shared vCPU, 1GB RAM - Production grade telemetry on a $5 / month virtual machine
- Quick Start
- Source Development
- Features
- Architecture
- Prerequisites
- Configuration
- Production Deployment
- Advanced Topics
- Testing
- Troubleshooting
- Resources
Canonical deployment source lives under deployments/ in this
monorepo. Standalone deployment repositories are designated one-way release
mirrors so operators can clone a small focused repository. Deployment changes
must be contributed to the canonical directories here; direct mirror changes
are overwritten by the release publication workflow.
If you want to use Junjo AI Studio rather than modify its source code, start with the generated Junjo AI Studio Minimal Build distribution mirror.
-
Clone the minimal build repository
git clone https://github.com/mdrideout/junjo-ai-studio-minimal-build.git cd junjo-ai-studio-minimal-build -
Choose setup mode
Recommended:
./scripts/junjo setup
Manual:
cp .env.example .env
Then generate and set secrets:
openssl rand -base64 32

openssl rand -base64 32

openssl rand -base64 32
Open
.envand replace the placeholder values:- Replace
your_base64_secret_hereinJUNJO_SESSION_SECRETwith the first generated value - Replace
your_base64_key_hereinJUNJO_SECURE_COOKIE_KEYwith the second generated value - Replace
your_internal_grpc_token_hereinJUNJO_INTERNAL_GRPC_TOKENwith the third generated value
For production deployments, also configure:
JUNJO_ENV=production
JUNJO_PROD_FRONTEND_URL=https://app.example.com
JUNJO_PROD_BACKEND_URL=https://api.example.com
JUNJO_PROD_INGESTION_URL=https://ingestion.example.com
- Replace
-
Start all services
docker compose up
-
Access Junjo AI Studio
- Follow the exact URL and port guidance in the minimal build README.
-
Create your first user
- Navigate to your frontend URL
- Follow the setup wizard to create your admin account
-
Create an API key (for sending telemetry from your Junjo app)
- Sign in to the web UI
- Open the API Keys page from the sidebar
- Click Create API Key
- Copy the 64-character key from the API Keys page (use the copy button)
- Use this key in your Junjo Python Library application
# View logs from all services
docker compose logs -f

# View logs from specific service
docker compose logs -f backend
docker compose logs -f ingestion
docker compose logs -f frontend

# Stop services (keeps data)
docker compose down

# Restart a specific service
docker compose restart backend

# View running containers and their status
docker compose ps

# Stop and remove all data (fresh start)
docker compose down -vConfigure your Junjo Python Library application using the setup and endpoint guidance from the minimal build repository.
Version compatibility: Junjo AI Studio and the Junjo Python Library must run releases that share the same telemetry contract. A mismatched SDK may still send raw spans, but Studio does not apply a fallback semantic parser: Workflow graphs, Agent diagnostics, and verified Store reconstruction require the active contract. Upgrade the paired releases together.
This repository contains the complete open source Junjo AI Studio codebase. If you want to run or modify the source code in this repository, see Source Development below.
For operator-managed deployment behind your own reverse proxy, use the
minimal distribution or the
VM/Caddy distribution, and provide explicit
JUNJO_PROD_* public URLs. Their standalone repositories are generated release
mirrors of these canonical directories.
This directory contains the complete open source Junjo AI Studio codebase. From the Junjo platform repository root, enter the Studio project before running its commands:
cd apps/studioUse the default hot-reload local stack when you want to develop or modify Junjo AI Studio itself:
./scripts/junjo setup
docker compose up --build
Local URLs use the same port numbers inside Docker and on localhost:
JUNJO_BUILD_TARGET=development: frontendhttp://localhost:26151, backendhttp://localhost:26154, OTLPgrpc://localhost:26155JUNJO_BUILD_TARGET=production: frontendhttp://localhost:26153, backendhttp://localhost:26154, OTLPgrpc://localhost:26155
The port numbers stay the same for same-network containers. Only the hostname changes: use backend:26154 for the backend API and ingestion:26155 for OTLP from another container on this Compose network.
After changing JUNJO_BUILD_TARGET, rerun docker compose up --build so Docker rebuilds the matching image targets. Use -d only when you intentionally want detached containers.
For service-specific development notes, see backend/README.md, frontend/README.md, and ingestion/README.md.
Observability & Debugging:
- View complete Workflow and Agent execution traces
- Explore declared Workflow Graph paths and realized Agent operation timelines
- Inspect normalized model requests/responses and Tool arguments/results
- Navigate backend-verified Workflow and Agent Store transitions
- Diagnose partial evidence, payload policy, and OTLP loss signals
- Follow semantic parents and causally nested Workflows or Agents
- Monitor performance and latency
OpenTelemetry Integration:
- Standards-compliant OTLP/gRPC ingestion endpoint
- Automatic trace collection from Junjo Python Library
- Custom span attributes for AI-specific metadata
Multi-Service Architecture:
- Decoupled ingestion for high throughput
- Web UI for visualization
- REST API for programmatic access
The Junjo AI Studio is composed of three primary services:
- Tech Stack: FastAPI (Python), SQLite, DataFusion
- Responsibilities:
- HTTP REST API
- User authentication & session management
- Span querying & analytics
- Semantic Workflow and Agent diagnostics
- Shared Store reconstruction and evidence-integrity verification
- Tech Stack: Rust, gRPC (tonic), Arrow IPC, Parquet
- Responsibilities:
- OpenTelemetry OTLP/gRPC endpoint
- High-throughput span ingestion with backpressure
- Write-Ahead Log using Arrow IPC segments
- Flush WAL to date-partitioned Parquet files (cold storage)
- Prepare hot snapshots for real-time queries
- Tech Stack: React, TypeScript
- Responsibilities:
- Web UI for Workflow Graph visualization
- Dynamic Agent operation timelines and evidence inspection
- Verified Store state navigation and nested executable links
- User management
Data Flow (Two-Tier Architecture):
Junjo Python App → Ingestion Service (gRPC) → Arrow IPC WAL
                                                    ↓
                                         ┌─────────┴─────────┐
                                         ↓                   ↓
                                    FlushWAL RPC    PrepareHotSnapshot RPC
                                         ↓                   ↓
                                  Parquet files         Hot snapshot
                                  (COLD tier)          (HOT tier)
                                         ↓                   ↓
                                         └─────────┬─────────┘
                                                   ↓
                                    Backend Service (DataFusion)
                                         ↓
                                  Merged query results
                                         ↓
                                     Frontend UI
How it works:
- Ingestion receives OTLP spans and writes them to Arrow IPC WAL segments
- FlushWAL (periodic/manual) converts WAL segments to date-partitioned Parquet files (COLD tier)
- PrepareHotSnapshot creates an on-demand Parquet file from unflushed WAL data (HOT tier) and returns a bounded list of recently flushed cold Parquet files (
recent_cold_paths) to bridge indexing lag - Backend uses DataFusion to query COLD (SQLite-indexed +
recent_cold_paths) and HOT Parquet files, merging results with deduplication by(trace_id, span_id)(COLD wins)
- Docker and Docker Compose (for contributor development and local smoke tests)
- Rust toolchain (for ingestion service development)
- Python 3.13+ with uv (for backend development)
- Node.js 18+ (for frontend development)
- A domain or subdomain for hosting (see Deployment Requirements)
- TLS termination in your chosen reverse proxy or ingress layer
Junjo AI Studio uses a single .env file at the root of the project. All services read from this file.
For a guided setup wizard that writes critical .env values (including memory tuning profiles), run:
./scripts/junjo setup# === Build & Environment ===========================================
# Build Target: development | production
JUNJO_BUILD_TARGET="development"
# Running Environment: development | production
# (affects cookie security, logging, etc.)
JUNJO_ENV="development"
# === Security (REQUIRED for production) ============================
# Generate each with: openssl rand -base64 32
JUNJO_SESSION_SECRET=your_base64_secret_here
JUNJO_SECURE_COOKIE_KEY=your_base64_key_here
JUNJO_INTERNAL_GRPC_TOKEN=your_internal_grpc_token_here
# === CORS ==========================================================
# IMPORTANT: Cannot use "*" with session cookies (credentials=True)
# Default: http://localhost:26151,http://localhost:26153
# Production: Auto-derived from JUNJO_PROD_FRONTEND_URL if not set
# Explicitly set for multiple frontends:
# JUNJO_ALLOW_ORIGINS=https://app.example.com,https://admin.example.com
# === Database Storage ==============================================
# Where database files are stored on your host machine/VM
JUNJO_HOST_DB_DATA_PATH=./.dbdata
# === Logging =======================================================
JUNJO_LOG_LEVEL=info # debug | info | warn | error
JUNJO_LOG_FORMAT=json # json | textSee .env.example for complete configuration with detailed comments.
Junjo AI Studio stores all database files in a single location that you configure. Simply set where you want the data stored on your host machine, and Docker handles the rest.
For local development, use a relative path:
# .env file
JUNJO_HOST_DB_DATA_PATH=./.dbdata
JUNJO_BUILD_TARGET=development
This stores databases in ./.dbdata directory next to your compose.yaml.
Docker can create the directory automatically for an ordinary first start. For
a greenfield reset, follow TESTING.md and create the empty shared root before
starting Compose so backend and ingestion do not race to create it.
Benefits:
- Easy to reset by deleting the directory
- No special setup required
- Works out of the box
For production deployments with persistent storage (DigitalOcean Volumes, AWS EBS, Google Persistent Disk):
1. Mount your block storage:
# DigitalOcean Droplet example
sudo mount /dev/disk/by-id/scsi-0DO_Volume_junjo /mnt/junjo-data

# AWS EC2 example
sudo mount /dev/xvdf /mnt/junjo-data

# Google Cloud example
sudo mount /dev/disk/by-id/google-junjo-data /mnt/junjo-data
2. Update your .env file:
JUNJO_HOST_DB_DATA_PATH=/mnt/junjo-data
JUNJO_BUILD_TARGET=production
3. Start services:
docker compose up --buildBenefits:
- Data persists across container restarts
- Data survives even if you delete and recreate containers
- Easy to backup by snapshotting the volume
- Can detach and reattach to different instances
- The
JUNJO_HOST_DB_DATA_PATHvariable is the ONLY path you need to configure - Container-internal paths are set automatically in
compose.yaml - If
JUNJO_HOST_DB_DATA_PATHis not set, it defaults to./.dbdata - The backend and ingestion services share the same storage location (the frontend is stateless and mounts no storage)
Junjo AI Studio uses embedded databases and file-based storage:
| Storage | Purpose | Type |
|---|---|---|
| SQLite | User data, API keys, sessions | Single file |
| Parquet | Span analytics (COLD tier) | Date-partitioned files |
| Arrow IPC WAL | Ingestion buffer (HOT tier) | Directory of IPC segments |
| Hot Snapshot | Real-time query cache | Single Parquet file |
All are stored under JUNJO_HOST_DB_DATA_PATH on your host machine. The backend uses DataFusion to query Parquet files directly.
After starting Junjo AI Studio:
- Sign in to the web UI exposed by your active build target (
http://localhost:26151for development,http://localhost:26153for production) - Open the API Keys page from the sidebar
- Click Create API Key
- Copy the 64-character key from the API Keys page (use the copy button)
- Use this key in your Junjo Python Library application
The Studio runtime root defines the production runtime contract:
- explicit public URLs via
JUNJO_PROD_FRONTEND_URL,JUNJO_PROD_BACKEND_URL, andJUNJO_PROD_INGESTION_URL - the frontend/backend same-domain requirement for session cookies
Supported deployment topology source is owned separately under
deployments/. Bring your own reverse proxy, ingress, or load
balancer around the minimal distribution, or use the
VM/Caddy distribution as a complete example.
If you route directly to this source repository's Compose services, target frontend:26153, backend:26154, and ingestion:26155.
Supported configurations:
- ✅
api.example.com+app.example.com(subdomain + subdomain) - ✅
api.example.com+example.com(subdomain + apex) - ✅
example.com+api.example.com(apex + subdomain) - ❌
app.example.com+service.run.app(different domains - will NOT work)
Why? Junjo AI Studio uses session cookies with SameSite=Strict for security (CSRF protection). Cross-domain deployments will cause authentication to fail.
The paths below are canonical. The linked standalone repositories are the generated release distributions for operator use, not contribution targets.
- Canonical source:
deployments/minimal - Designated release mirror: mdrideout/junjo-ai-studio-minimal-build
A minimal, standalone repository with just the core Junjo AI Studio components using pre-built Docker images.
Best for:
- Quick testing of Junjo AI Studio
- Simple production deployments with explicit public URLs
- Integration into existing infrastructure
- Canonical source:
deployments/vm-caddy - Designated release mirror: mdrideout/junjo-ai-studio-deployment-example
A complete, production-ready example that includes a Junjo Python Library application alongside the server infrastructure.
Best for:
- End-to-end deployment examples
- Learning how to configure your Junjo app with the server
- VM deployment guide (Digital Ocean Droplet, AWS EC2, etc.)
- One complete reverse-proxy/TLS example
The canonical VM/Caddy README provides step-by-step deployment instructions.
Junjo AI Studio is built and deployed to Docker Hub with each GitHub release:
- Backend: mdrideout/junjo-ai-studio-backend
- Ingestion Service: mdrideout/junjo-ai-studio-ingestion
- Frontend: mdrideout/junjo-ai-studio-frontend
Example Compose file: deployments/minimal/docker-compose.yml
Use these images in the deployment stack you own. For complete working examples, start from the minimal-build or deployment-example repositories.
Junjo AI Studio is designed to be low resource:
- Minimum: Shared vCPU + 1GB RAM
- Databases: SQLite (embedded, low overhead)
- Recommended: 1 vCPU + 2GB RAM for production workloads
Applications should persist Junjo Workflow or Agent runtime IDs, not OpenTelemetry trace/span IDs. A signed-in Studio user can follow a stable frontend link of this form:
/resolve/executable?service_namespace=junjo.examples&service_name=ai-chat&executable_type=agent&runtime_id=<run-id>&destination=detail
The authenticated frontend renders the semantic execution page immediately. While telemetry is still arriving, it shows an in-context pending message and continues exact resolution with capped backoff. When the execution becomes available, Studio replaces the semantic URL with the ordinary Agent, Workflow, or full-trace detail URL. One-Node Workflows open with that exact Node selected. Resolution requires service namespace, service name, executable type, and runtime ID. Multiple matching owner spans are an explicit conflict and Studio never selects the newest match. Applications do not receive a Studio API credential to construct or follow these links.
The ingestion service stores spans in Parquet files. You can inspect them using Python.
import pyarrow.parquet as pq

# Read cold tier
table = pq.read_table('.dbdata/spans/parquet/')
print(f"Cold tier spans: {table.num_rows}")

# Read hot snapshot
hot = pq.read_table('.dbdata/spans/hot_snapshot.parquet')
print(f"Hot tier spans: {hot.num_rows}")The backend container exclusively owns the live SQLite database and its WAL
files. Use Studio's HTTP APIs while the stack is running; do not open the
bind-mounted database with a host SQLite process. Stop the complete stack before
offline maintenance. The greenfield reset and setup flow is documented in
TESTING.md.
- Ingestion throughput: Adjust ingestion tunables in
.env(see.env.example, e.g.BATCH_SIZE,FLUSH_MAX_MB,FLUSH_MAX_AGE_SECS,BACKPRESSURE_MAX_MB) - Database performance: SQLite uses WAL mode for better concurrency
- Container resources: Increase memory limits if processing high span volumes
Junjo AI Studio has comprehensive test coverage across all services. Tests are organized to support both local development and CI/CD pipelines.
# Run all tests (backend, frontend, contract validation, proto validation)
./run-all-tests.sh
This script runs: 0. Proto version checking - Warns if the system compiler used by Rust does not match v30.2
- Python linting - Runs ruff check on backend code (matches pre-commit validation)
- Backend tests - Unit, integration, and gRPC tests (Python/pytest)
- Ingestion tests - Rust unit/integration tests (Cargo)
- Frontend tests - Unit, integration, and component tests (TypeScript/Vitest)
- Contract tests - Validates frontend ↔ backend API schema compatibility
- Proto validation - Regenerates protos and validates staleness
Run everything:
./run-all-tests.sh- Complete test suite for all services
Backend-specific:
./backend/scripts/run-backend-tests.sh- All backend tests (unit, integration, gRPC)./backend/scripts/validate_rest_api_contracts.sh- Contract tests (schema validation)
Frontend-specific:
cd frontend && npm run test:run- All frontend tests (exits after completion)cd frontend && npm test- Frontend tests in watch modecd frontend && npm run test:contracts- Contract tests only
Individual services:
- Backend: See backend/README.md for detailed test categories
- Frontend: See TESTING.md for testing strategy and frontend/README.md for frontend commands
- Ingestion: See ingestion/README.md for Rust tests
Junjo AI Studio uses a centralized root VERSION file for release/app metadata synchronization.
# Sync all managed version fields from VERSION
./scripts/sync-version.sh

# Set a new version and sync everything
./scripts/sync-version.sh 0.82.0

# Verify all managed files are in sync with VERSION
./scripts/check-version-sync.sh
Managed files include backend (pyproject, FastAPI metadata, OpenAPI), ingestion (Cargo.toml/Cargo.lock), and frontend (package.json/package-lock.json).
Release guardrail: Docker publish workflow validates that the GitHub release tag exactly matches VERSION.
Understanding what each validation tool does helps avoid surprises at commit time.
| Validation | run-all-tests.sh | pre-commit hook | CI (GitHub Actions) |
|---|---|---|---|
| Proto version check | ✅ Warns | ✅ Warns | ✅ Enforces |
| Python linting (ruff) | ✅ Fails | ✅ Auto-fixes + fails | ✅ Enforces |
| Backend tests | ✅ Runs all | ❌ | ✅ Enforces |
| Ingestion tests | ✅ Runs all | ❌ | ✅ Enforces |
| Frontend tests | ✅ Runs all | ❌ | ✅ Enforces |
| Contract tests | ✅ Validates | ❌ | ✅ Enforces |
| Proto regeneration | ✅ Regenerates | ✅ Regenerates + stages | ✅ Checks staleness |
| Proto staleness check | ✅ Fails on diff | ❌ (auto-fixes) | ✅ Enforces |
During development (before committing):
# Option 1: Run everything at once (recommended)
./run-all-tests.sh

# Option 2: Run individual validations
cd backend && uv run ruff check app/          # Linting
./backend/scripts/run-backend-tests.sh        # Backend tests
cd ingestion && cargo test                    # Ingestion tests
cd frontend && npm run test:run              # Frontend tests
./backend/scripts/validate_rest_api_contracts.sh  # Contracts
At commit time:
git commit
# Pre-commit hook runs automatically:
# - Checks proto versions (warns if wrong)
# - Regenerates proto files (stages changes)
# - Runs orphan detection (blocks if missing .proto files)
# - Runs ruff format (auto-fixes Python style)
# - Runs ruff check (blocks if linting errors)
Philosophy:
- run-all-tests.sh: Comprehensive validation during development - catches issues early
- pre-commit hook: Safety net + auto-fixes - ensures commit quality
- CI: Final enforcement - prevents merging broken code
Why run-all-tests.sh matches pre-commit:
Previously, run-all-tests.sh could pass but pre-commit would fail (orphaned schemas, linting errors). This wasted developer time debugging at commit stage. Now both tools perform the same core validations, with pre-commit adding auto-fixes.
Result: No surprises at commit time. If run-all-tests.sh passes, pre-commit will too (except for auto-fixable style issues).
Junjo AI Studio uses contract testing to prevent frontend/backend API drift. Backend Pydantic schemas are the single source of truth, validated against frontend TypeScript/Zod schemas using OpenAPI-generated mocks.
How it works:
- Backend exports OpenAPI schema from Pydantic models
- Frontend tests generate mocks from OpenAPI spec
- Zod schemas validate they can parse the mocks
- Tests fail if schemas drift
Run contract tests:
./backend/scripts/validate_rest_api_contracts.shSee backend/scripts/README_SCHEMA_VALIDATION.md for detailed documentation.
Tests run automatically on all PRs via GitHub Actions:
../../.github/workflows/studio-backend-tests.yml- Backend test suite../../.github/workflows/studio-rest-api-contract-validation.yml- REST API contract tests../../.github/workflows/studio-proto-staleness-check.yml- Proto file validation../../.github/workflows/studio-version-sync-check.yml- Version drift validation againstVERSION
Symptom: Can't sign in, or immediately signed out after login.
Causes & Solutions:
-
Multiple Junjo instances on localhost
- Old session cookies from another instance may interfere
- Fix: Clear browser cookies for
localhostand restart services
-
Cross-domain deployment (most common in production)
- Frontend and backend on different top-level domains
- Fix: Ensure both services share the same registrable domain (see Deployment Requirements)
-
Missing or invalid secrets
JUNJO_SESSION_SECRET,JUNJO_SECURE_COOKIE_KEY, orJUNJO_INTERNAL_GRPC_TOKENnot set correctly- Fix: Generate new secrets with
openssl rand -base64 32
-
CORS misconfiguration
- Frontend URL not in
JUNJO_ALLOW_ORIGINS - Fix: Add your frontend URL to the CORS origins list
- Frontend URL not in
Hosted deployment troubleshooting lives with the deployment stack you choose. For working examples, start from the minimal-build or deployment-example repositories.
Symptom: Error: bind: address already in use
Solution:
# Find process using the port
lsof -i :26151  # or :26153, :26154, :26155, etc.

# Kill the process
kill -9 <PID>Symptom: Services fail to start or health checks fail
Solutions:
-
Check logs
docker compose logs backend
docker compose logs ingestion
docker compose logs frontend
-
Clear volumes and rebuild
docker compose down -v
docker compose up --build
-
Check .env file
- Ensure all required variables are set
- Secrets must be base64-encoded 32-byte values
Symptom: Database errors or corruption warnings
Solution:
# Stop services
docker compose down

# Backup and clear database files
mv .dbdata .dbdata.backup

# Restart (will create fresh databases)
docker compose up --build- Junjo Python Library - explicit Workflow and bounded Agent execution framework
- Canonical minimal source — minimal setup with pre-built images; also published as the minimal-build mirror.
- Canonical VM/Caddy source — complete VM example with one reverse-proxy implementation; also published as the deployment-example mirror.
- junjo-ai-studio-backend - FastAPI backend
- junjo-ai-studio-ingestion - Rust gRPC ingestion service
- junjo-ai-studio-frontend - React frontend
- OpenTelemetry Documentation - OTLP specification
- OpenTelemetry Python - Python SDK
Junjo AI Studio - Making AI Workflow and Agent executions transparent and understandable.
Copyright (C) 2025 Matthew Rideout
Junjo-authored Studio source is licensed under the Apache License, Version 2.0.
See LICENSE. Incorporated third-party source and historical
provenance are documented in
THIRD_PARTY_NOTICES.md.